

sandbox tool, the
model writes and runs Python in the sandbox. It searches the web, deduplicates
and classifies results, fixes errors, and reruns the code, all server-side.
You never run any analysis or charting code locally: the
script just submits the requests, polls the background responses, and downloads
the finished PDF. Every number on the chart is computed, not guessed.
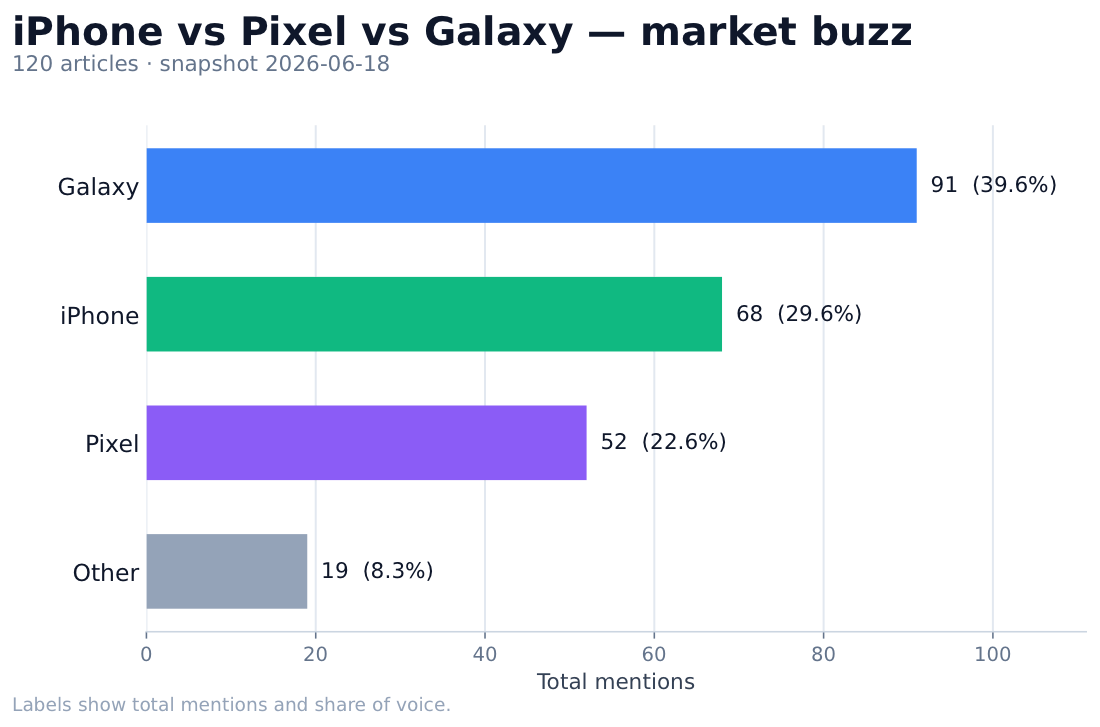
One run over a basket of 15 phone-news queries: each brand's share of voice, counted from the search results inside the sandbox and rendered to a PDF.
What the sandbox does here
- Runs the analysis as code, not from memory. Like a code interpreter, the
sandbox lets the model solve a quantitative task by writing and running Python
instead of guessing. The mention counts and share-of-voice percentages come
from code it executed over the search results, not from guesses. The script
enforces this: it checks the response
contains a
sandbox_resultsitem and refuses the result otherwise, so the model can’t skip the tool and return invented counts. - Searches the web in the same run. The sandbox can reach Perplexity search from inside the run, so the model pulls the articles itself and classifies them in the same request, with no separate scraping step, glue code, or extra tool to wire up.
- Returns a PDF without a local charting runtime. matplotlib and the
runtime live in the sandbox; the model renders the chart, shares it with
share_file, and you download the.pdffrom the response by id. One request in, one file out, and no charting runtime to install or host locally. A plain chat completion would only return text.
Without the sandbox
To build the same report yourself, you’d stand up a runtime: a machine with Python and matplotlib, the search and classification code, and somewhere to execute it and capture the file. With thesandbox tool the model writes and
runs that code server-side and hands back the finished PDF. You do not run the
analysis or rendering code locally. The model adapts the code to whatever the search
returns, so you don’t have to maintain a fixed pipeline.
Installation
Keep the project files in the same directory:competitor_buzz_tracker.py, observability.py (imported by the script),
requirements.txt, and your basket.yaml.
- Install the dependencies: the Perplexity Python library,
PyYAML (to read the basket config), and Pydantic (for the response schema).
They’re pinned in
requirements.txt:
requirements.txt
- Set your Perplexity API key:
This example uses the Agent API
sandbox tool. See the
Sandbox docs for
setup and usage details.Usage
You describe the job in a small YAML basket: a chart title, the search queries to run, and the keyword rules that classify each result. One article can match several keywords. A story that mentions both Pixel and Galaxy counts for both; one that matches none counts under “Other”. More queries mean broader coverage.basket.yaml
regex is a single case-insensitive pattern. Use | for
alternatives (e.g. "galaxy|samsung"). Save it as basket.yaml, then run:
competitor-buzz-<date>_<time>.pdf to the current directory. Add
--show-code to also print the Python the agent wrote and ran in the sandbox.
How it works
You describe the job in plain language and hand the model thesandbox tool;
from there it writes the Python, runs it, fixes its own errors, and hands back
the counts and the chart. You never touch the analysis code yourself.
This example splits that work across two chained requests rather than one.
Analysis and rendering are different jobs, and splitting them keeps each prompt
short, lets you run the mechanical step on a lower-priced model (openai/gpt-5.6-terra) and
the rendering on the flagship (openai/gpt-5.5), and puts an inspectable
checkpoint in the middle.
Request 1 (analytics) gets the sandbox tool and a
response_format
schema. The model searches each query from inside the sandbox, pools the
results, deduplicates by URL, regex-matches each article against the keyword
rules, and counts mentions per brand plus its share of voice. The schema turns
its answer into a typed contract instead of prose:
sandbox tool, then renders
the horizontal bar chart to report.pdf and shares it with share_file.
There’s no shared memory between the two: the script validates request 1’s JSON
against the schema and passes it into request 2, so the intermediate is plain
data you can print or unit-test before anything is drawn. Both requests run with
background=True and are polled until they finish, because a sandbox run can
take a while.
Prompting guidance
You don’t write the analysis code. Each request describes its job as a plain prompt, about as long as a chat message, and the model turns that into Python it runs in the sandbox. The analytics request just sends the basket’s queries and keyword rules as its prompt:See the Python the agent wrote (--show-code)
See the Python the agent wrote (--show-code)
With It’s regular Python you can read and check, with no framework or hidden
state. The model writes fresh code each run, so the exact code varies between
runs.
--show-code, the script prints every sandbox cell the model ran. On the
run above the analytics agent took five cells (including one to inspect a search
result’s fields) before settling on the code below. The condensed code shows
what it executed: search each query,
canonicalize and deduplicate URLs, regex-classify each result, count mentions,
and print the JSON the schema expects.pplx_sdk is the search interface available inside the sandbox.Full code
The script is one file; cost reporting and the--show-code helper live in a
small observability.py beside it (off the critical path, so it’s easy to drop
or move into shared tooling later).
Full code: competitor_buzz_tracker.py and observability.py
Full code: competitor_buzz_tracker.py and observability.py
Example Output
A run ofpython competitor_buzz_tracker.py --config basket.yaml.
Results vary with live coverage:
snapshot <date>. Every count comes from search results the model actually
classified with the keyword rules, not from its training data. (Shares are
rounded to one decimal, so they may not sum to exactly 100%.)
Limitations
- Coverage varies. Output depends on live news, so counts differ by topic and over time.
- Billing. This makes two Agent API requests, so each run is billed for two sets of model tokens, the started 20-minute blocks of sandbox container time in each request, and the SDK web searches made inside the sandbox in request 1. See Tool Pricing.